
Over the past several years, the parquet file format has become the gold standard for storing large volumes of analytical data. Compatible with many databases and data transformation tools, packed with compression and encoding techniques, and capable of retaining schemas across an array of data types, it’s not hard to see why.
Since parquet is an integral part of how Tabsdata efficiently stores and manages data, I was curious what exactly was under the hood that made this file storage format so powerful.
Why Was Parquet Created?
Before the rise of big data, most mainstream data infrastructure was optimized primarily for transactional workloads (OLTP). These workloads were characterized by high-frequency, low-latency, and small row-level reads and writes.
During the early 2000s, the rapid adoption of the internet caused a major paradigm shift in the data ecosystem. Companies like Google and Yahoo produced massive volumes of query and clickstream logs, while social media platforms like Facebook and Twitter generated continuous streams of user activity and telemetry data.
Traditional vertically scaled systems became economically and technically inefficient at handling these workloads at scale.
An alternative approach emerged in the form of horizontal scaling, spearheaded by Hadoop and the Hadoop Distributed File System (HDFS). Hadoop distributed storage and computation across clusters of inexpensive hardware.
Although Hadoop solved many of the infrastructure challenges surrounding distributed storage and compute, a new bottleneck quickly emerged: efficiently storing, serializing, and analyzing large analytical datasets.
At the time, all this data was commonly stored in semi-structured, row-oriented formats such as CSV and JSON. These formats were poorly suited for analytical workloads because they required scanning entire rows even when queries only needed a small subset of columns. They also suffered from poor compression, expensive parsing overhead, limited schema enforcement, and inefficient predicate filtering.
Parquet was invented by Twitter and Cloudera in 2013 to address these exact limitations.
What Makes a Good File Format
A good file format can be broadly evaluated across four dimensions:
- Data Retrieval: How can you retrieve data from this format using the least amount of time and resources (memory, disk, etc.)?
- Data Storage: How can you store the most data using the least amount of storage space?
- Data Fidelity: How closely does the format preserve the original structure and meaning of the source data?
- Compatibility: How well adopted is this format? How well does it integrate with other systems?
Data Retrieval
Columnar vs Row-Based Storage
CSV and JSON are both row-oriented data formats. This means they organize data by storing records row by row.
Think about the data in the image above. In a row-oriented format, the first record would be [1, “john”, 4.1].
Parquet, on the other hand, uses columnar storage. In the same dataset, the first section of data in a columnar system would be id = [1, 2, 3].
So What
Row-based storage is an efficient approach for OLTP (Online Transaction Processing) workloads, where entire rows are frequently inserted, updated, or deleted. This is because records are stored together contiguously, making row-level operations efficient.
However, when it comes to OLAP (Online Analytical Processing), these strengths quickly become weaknesses.
Real-World Applications of Row vs Columnar Filing
Imagine you are a cashier in a store and your job is to record the purchases people make.
In a row-based system, every time someone makes a purchase, you take a new slip of paper and write the item name, transaction date, and the price on the same slip.
In a columnar system, you instead keep three separate notebooks. When someone makes a purchase, you open one notebook and write down the item name, then open another notebook and write down the price, then open the last notebook and write the transaction date.
For processing real-time transactions, the row-oriented system wins. When someone makes a purchase, the cashier only needs to access a single sheet of paper to write everything down (insert). If someone returns an item, the cashier can just find that receipt and throw it out (delete).
However, imagine it’s the end of the month and the store manager needs to find out how much revenue the store generated. In a row-oriented system, the manager has to go through every single receipt, find the ones from this month, scan each receipt to locate the price, then store and sum all those values together.
In a columnar system, all the prices are in a single notebook. The manager just needs to find the relevant section of purchase amounts and add them together. Since the manager only cares about revenue, they do not need access to unrelated data like item names.
Row-oriented storage is better for the cashier while they are recording purchases, whereas columnar storage is better for the manager when they need to analyze that transactional data.
OLAP Shifting the Ecosystem
For analytical processing, query engines generally need to fetch data, scan through it, and then prune the dataset down to the subset of rows (predicates) and columns (projections) required for the query.
Take our 3×3 table from the image earlier. If we run SELECT name FROM table, a row-oriented system has to scan all 9 values in the table, even though the query only returns john, mike, and sally.
This means 66% of the scanned data was unnecessary I/O.
Projection Pushdown
Take our same query SELECT name FROM table, but query it from columnar storage. Since data is grouped by column, the engine only needs to scan the name column.
This is projection pushdown, a retrieval technique that saves I/O by only reading data from specific columns, rather than the entire dataset.
Row Grouping
Columnar storage provides the ability for projection pushdown, but it also creates an unintended consequence. Generally, datasets have more rows than columns.
In a row-oriented system, all attributes for a single record are stored together. This naturally bounds how much data a query engine needs to load when accessing individual records. Pure columnar storage flips this on its head.
Say we have a 6-column × 1,000,000-row table. Pulling a single column from this table in a columnar format means potentially processing 1,000,000 values at once.
This also makes it more difficult to apply predicates to queries.
This is why parquet does not use purely columnar grouping. Instead, it uses a hybrid of columnar and row-based grouping through row groups.
Row groups split a dataset into chunks of rows. Inside each row group are column chunks containing the values for each column within that subset of rows.
Predicate Pushdown
Whereas projection pushdown is a retrieval technique that avoids scanning unnecessary columns, predicate pushdown avoids reading unnecessary rows. In parquet, this is largely facilitated through row groups and the metadata attached to them.
Row Group Metadata
Each column chunk inside a row group is given metadata that facilitates predicate pushdown. Parquet stores statistics like minimum and maximum values for each column chunk.
This is especially useful for queries using numerical predicates. For example, imagine we run the query SELECT id, score FROM table WHERE score > 10 on the dataset in the picture above.
Whereas a row-based system would still need to scan every value in every row, parquet can use row group metadata to skip large portions of the dataset entirely.
For example:
- Omit scanning Row Group 1 because the maximum value for score is 6.4 ❌
- Omit scanning Row Group 3 because the maximum value for score is 8.6 ❌
- Scan Row Group 2 because its score range may contain matching values ✅
- Within Row Group 2, omit the name column chunk because it is not included in the query projection ✅
Through predicate and projection pushdown, we omit scanning 78% of our dataset. WOW!
This also works with string data. String statistics are generally stored alphabetically, which still allows some predicate pushdown, but typically with less precision than numerical ranges.
Bloom Filtering
Bloom filtering is another nifty heuristic parquet can implement to increase the efficiency of data retrieval.
As mentioned earlier, min/max metadata is considerably less effective for string data than numerical data. Take the set ["mac", "jack", "brenda"]. We know the alphabetical minimum value is brenda and the maximum value is mac. This tells us the dataset:
- includes brenda
- includes mac
- does not include names alphabetically before b or after m, like adam
However, this metadata cannot tell us whether a name between b and m exists, like jason.
Bloom filtering helps fill this gap by creating a compact bit store of n bits. Each value in a column chunk is run through multiple hash functions. The outputs of those hash functions are then modulo-divided by n, converting them into indexes between 0 and n - 1.
The bloom filter then sets the bits at those indexes to 1.
When a query containing a predicate is executed, the predicate value is first run through the same hash and modulo operations. The resulting indexes are then checked against the bloom filter.
If any of those indexes contain a 0, parquet knows the value definitely does not exist in that column chunk, allowing the engine to skip scanning that portion of the dataset entirely.
If all indexes contain 1, the value might exist, so the engine still needs to scan the data. This means bloom filters can produce false positives, but never false negatives.
In the example above, the set [“mac”, “jack”, “brenda”] creates a bit store of 11010100. This means there is a value of 1 at indexes 0, 1, 3, and 5.
Now let’s see what happens when we check different predicate values through our bloom filter:
- Jason returns 0, 1, 7. The 7 index value is 0 in our bit store. They are definitely not in our column chunk ❌
- Mac returns 1, 0, 3. They might be in our column chunk ✅
- Cole returns 3, 5, 1. They might be in our column chunk ✅
Notice that bloom filtering does not rule out false positives, and that’s the beauty of it; it does not have to. This allows parquet to avoid scanning row groups for values like jason at the cost of a small amount of additional memory and disk space.
This all operates on the assumption that the I/O required to scan a row group is more expensive than evaluating the predicate value against the bloom filter.
Dataset Partitioning
In modern data systems, parquet datasets can be split (or partitioned) across many parquet files instead of existing as a single large file. For example:
events/year=2024/month=01/part-001.parquet
Even though this dataset consists of many parquet files, query engines still treat it as a single logical table because all files share the same schema.
Partitioning allows query engines to skip entire files before they are even opened. For example, if a query only requests data from year=2025, the engine can completely ignore the year=2024 directory.
Data Storage
Data Encoding and Compression
Parquet implements several encoding and compression techniques that seek to minimize the space required to store your data.
To demonstrate how impactful this is, I ran a little experiment where I grabbed the entire script of the first Shrek movie and stored it in a 1-column table.
I then created 1-row, 100-row, and 1,000-row versions of this dataset and stored each dataset on disk in CSV and parquet file format.

Lastly, I analyzed the file sizes of each of my six files.

As the results show, while my CSV file size increases by 38 KB for every row added to my dataset, my parquet files stay at 324 KB regardless of how many rows I add.
But how is this possible?
Columnar Compression
In row-oriented storage, different data types are intermixed:
[1, "john", 4.1]
This creates high variability between adjacent values, making compression more difficult.
Columnar storage, on the other hand, ensures every value in a group has the same type:
[1, 2, 3] ["john", "mike", "sally"] [4.1, 3.5, 6.4]
Because groups have the same type, it is easier to apply encoding and compression techniques.
Dictionary Encoding
This encoding technique converts unique values in a dataset into an ID map, then references those IDs instead of repeatedly storing the raw values.
In our example, the CSV stores the entire Shrek script in every row, which causes the file size to grow as the row count scales. Parquet, on the other hand, assigns the script text an ID of 1 and stores the raw script only once inside the dictionary. The remaining rows then reference that dictionary entry using the ID.
Run-Length Encoding
Let’s say we have already applied dictionary encoding.
We now have the ID 1 repeated for every row. While much smaller than repeatedly storing the full Shrek script, storage still scales linearly as rows are added, just now by the size of the ID instead of the full string.
Run-length encoding improves this further by compressing consecutive repeating values into a run, representing the data as a value and a count.
Bit Packing
A bit is the smallest unit of binary data, and the number of bits used determines the range of values that can be represented.
The more bits you use, the larger the range of representable values becomes, but the more storage space each value consumes.
When encoding values, parquet optimizes this by using the smallest number of bits required to represent the data. For example, if our dataset only contains values ranging from 1–7, parquet can bit-pack the values using just 3 bits per value instead of a larger integer representation, reducing storage usage even further.
Compression Support
While encoding changes how values are represented within a dataset, compression is an additional layer of optimization that reduces the physical binary footprint of the resulting parquet data.
After parquet applies dictionary and run-length encoding to our dataset of repeating Shrek scripts, it can further reduce the binary footprint of the encoded parquet pages using compression codecs such as Snappy, GZIP, ZSTD, or Brotli.
Data Fidelity
Embedded Schema Definition
File formats can range from unstructured to structured. Text files, for example, are unstructured because there is no defined schema or data model. This provides flexibility, but makes parsing the data more difficult.
CSV and JSON both provide some degree of structure, but neither strongly enforces a consistent schema.
CSVs organize data into rows and columns, but all values are ultimately stored as text. For example, if someone inserts a string into a column intended for integers, the CSV will not raise any errors. The issue is only discovered later when a system attempts to cast that value into an integer.
CSVs also do not inherently enforce consistent row structure. Rows can contain missing values, extra values, or malformed formatting.
When I first started working with data and used CSVs for everything, I would bang my head against the wall when my processed CSV files would convert every é to é. Thankfully, this is something parquet has no issue with.
JSON has a similar issue because each record is its own independent object, meaning there are no inherent guarantees that an array of JSON records follows a consistent schema.
Parquet files, on the other hand, include embedded metadata that explicitly defines the schema and structure of the dataset. Columns are strongly typed, allowing systems writing parquet files to better enforce schema consistency during write operations.
This also means systems interacting with parquet files can understand the structure and schema of the dataset without first needing to fully materialize and inspect the raw data.
Primitive Data Type Support
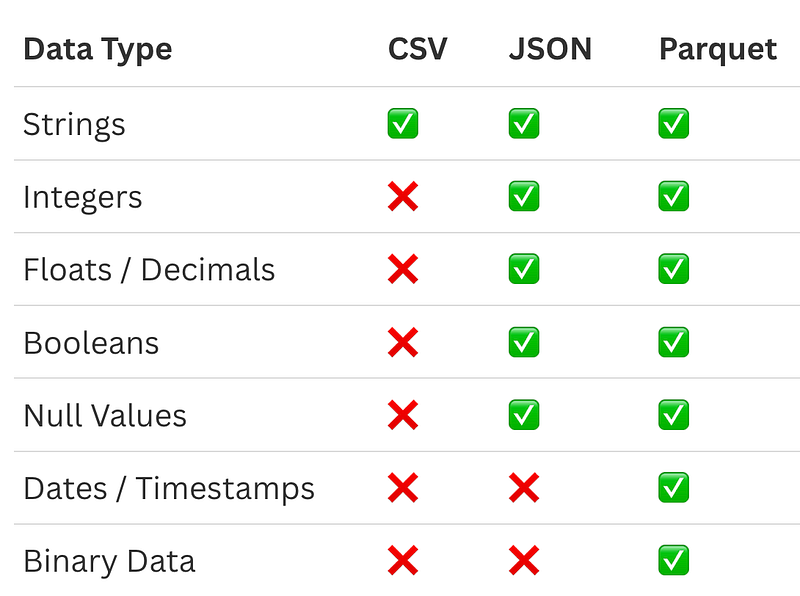
Parquet supports primitive data types such as strings, integers, floats, booleans, null values, dates, datetimes, and binary data.
While JSON supports some of these data types, CSV files store all data as plain text. This creates two major downstream consequences in data engineering workloads:
Downstream Type Casting
Imagine a producer wants to send data from Postgres to a consumer in Snowflake through CSV. If one of the columns is an integer, converting the data into CSV forces that integer into a string.
It then becomes the responsibility of the Snowflake consumer to cast the column back into an integer. This creates additional processing overhead and introduces more opportunities for type-related errors.
Data Loss
Now imagine the producer wants to send a datetime field instead.
Datetimes can have external string representations that omit precision or timezone information while still retaining that information internally. However, when timestamps are flattened into string format, much of this semantic information can become lost unless it is explicitly encoded into the string.
Parquet avoids this problem by preserving the full timestamp semantics.
Non-Primitive Data Type Support

Parquet supports non-primitive data types like lists and dictionaries. While JSON also supports both, it lacks the strongly typed schema metadata parquet embeds directly alongside the data.
CSVs, on the other hand, flatten non-primitive data structures into text representations.
Note: There is an interesting consequence non-primitive data types have on parquet file sizes. Unlike primitive data types, nested objects do not receive parquet’s dictionary encoding and run-length encoding. While parquet can still dictionary-encode primitive values inside nested data, there is no compression of the structural overhead required to represent deeply nested objects, which can significantly increase file sizes.
I encountered this phenomenon while benchmarking Airbyte vs Tabsdata. Airbyte appended a column containing a dictionary that itself contained a list of dictionaries. Even though the values in this column were mostly empty lists and dictionaries, it more than doubled my parquet file size because parquet still had to represent the nested object structure for every row.
Because CSV flattens objects into text, this storage bloat only appeared during parquet export.
Compatibility
Parquet is highly compatible with our modern data ecosystem.
Unlike traditional database systems like Postgres, where storage and querying are tightly coupled to the database server, parquet exists independently from any single query engine or compute framework.
Because parquet files are portable and self-describing, many different tools can operate on the same dataset. A parquet dataset written by Spark can later be queried by DuckDB, Trino, Athena, or Snowflake, transformed with Polars or Pandas, cataloged through systems like AWS Glue, or managed through table formats like Iceberg.
This flexibility allows parquet to act as a shared storage layer across the modern data stack.
This is one of the reasons Tabsdata utilizes parquet for internal storage. If many modern data platforms already communicate natively through parquet, data movement becomes significantly faster and simpler because systems can operate much closer to the file layer rather than repeatedly materializing and reconstructing row-oriented representations of the data.
This is one of the reasons Tabsdata was 86x faster than Airbyte during benchmarking. Whereas Tabsdata could read and write parquet datasets directly, Airbyte incurred significantly more overhead from reading a parquet file row-by-row before writing it back into parquet.
Conclusions
Parquet is heavily optimized for analytical processing, largely as a result of the changing data ecosystem where analytical workloads became increasingly valued by companies and data platforms moved to be increasingly decoupled and interoperable.